NVIDIA HGX B300 GPU Servers: The Enterprise AI Infrastructure Guide for UAE Data Centres
From Blackwell Ultra architecture to high-density colocation, discover what it takes to deploy next-generation AI compute at scale.
The growth of generative AI is changing how enterprises plan computing infrastructure. Large language models, multimodal applications and production inference demand more than powerful processors: they require fast GPU-to-GPU communication, substantial memory, high-throughput storage and dependable data centre capacity. The NVIDIA HGX B300 platform addresses the compute layer. The harder commercial question is how to deploy and operate it efficiently.
At BitHash, our enterprise colocation approach connects AI hardware planning with the practical requirements of rack space, electrical capacity, cooling, connectivity and ongoing operations in the UAE.
What is NVIDIA HGX B300?
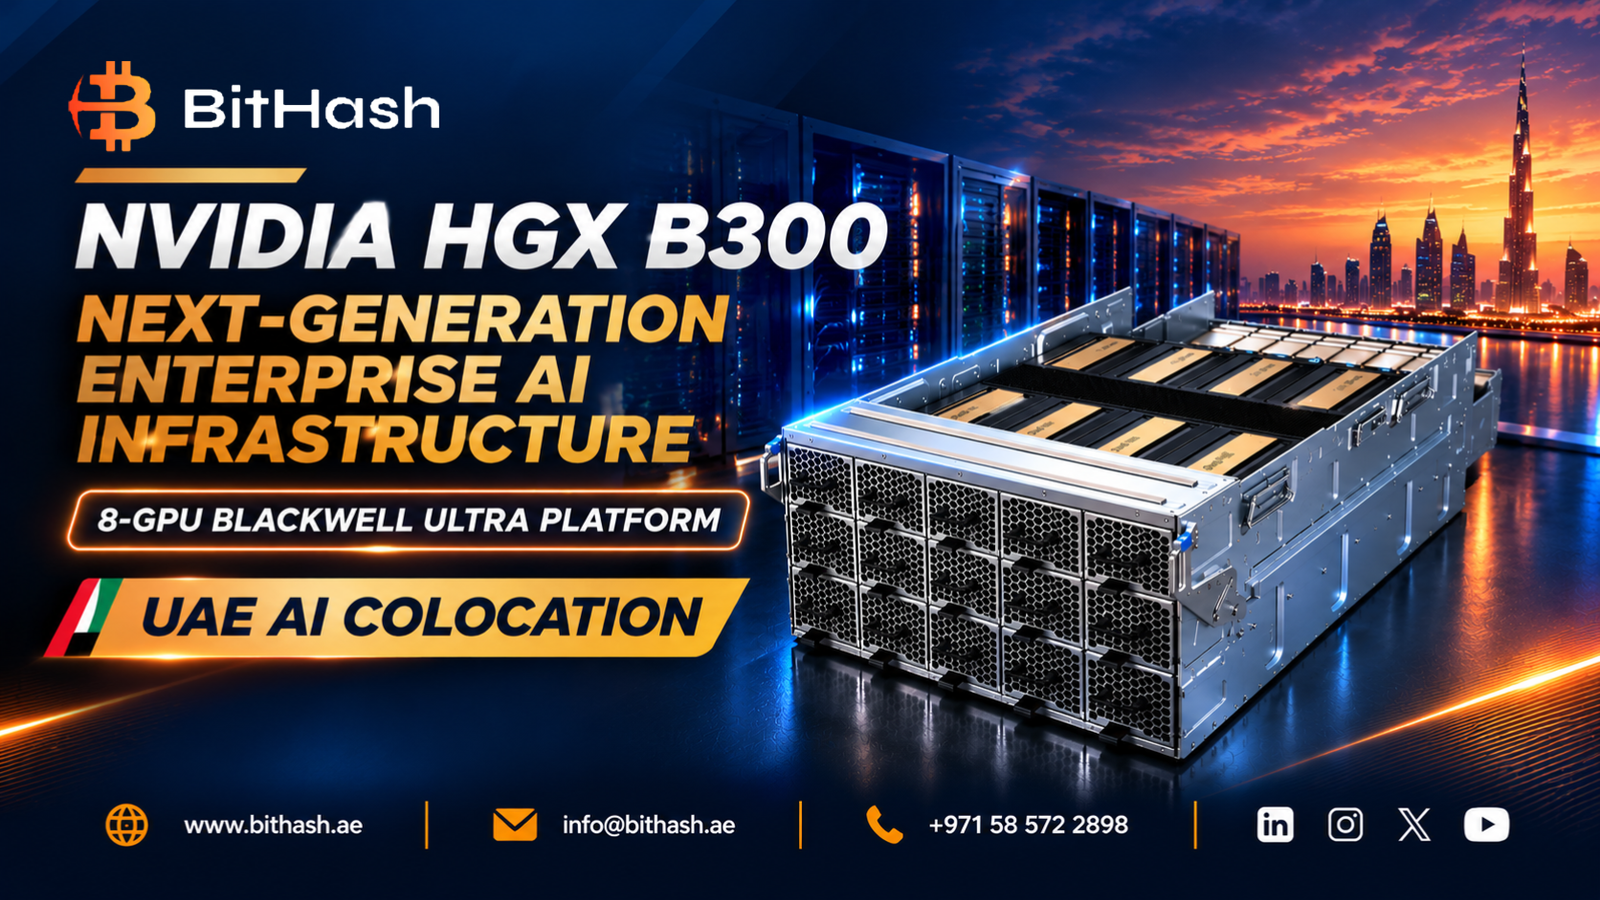
NVIDIA HGX B300 is an eight-GPU server platform based on NVIDIA Blackwell Ultra architecture. The GPUs communicate through NVIDIA NVLink and NVSwitch technology, designed to support data-intensive AI training and inference. Server configurations vary by manufacturer and integrator, so buyers should validate the complete bill of materials rather than relying on GPU model names alone.
Why the B300 matters for enterprise AI
More accelerator memory: Higher memory capacity can help accommodate larger models, longer contexts and demanding inference workloads. High-speed interconnect: NVLink and NVSwitch reduce communication bottlenecks within an eight-GPU node. Cluster readiness: High-speed networking, storage and orchestration enable multiple servers to operate as a coordinated AI environment. Real-world gains depend on workload, software configuration and cluster architecture.
NVIDIA HGX B200 vs HGX B300: What changes?
| Evaluation factor | HGX B200 | HGX B300 |
| Architecture | Blackwell | Blackwell Ultra |
| Memory | HBM3e | Higher-capacity HBM3e |
| GPU interconnect | NVLink / NVSwitch | NVLink / NVSwitch |
| Deployment focus | Large-scale training and inference | Larger models and dense inference |
| Facility planning | High-density infrastructure | High-density, cooling-critical infrastructure |
The right platform is determined by model size, memory needs, utilization targets and total cost of ownership—not simply the newest generation.
Enterprise use cases for NVIDIA B300 GPU servers
Foundation-model development: Training and fine-tuning complex language and multimodal models. AI inference: Serving high volumes of requests with demanding latency and context requirements. Research and HPC: Accelerating scientific, engineering and data-intensive workloads. Private enterprise AI: Supporting dedicated infrastructure where organizations require greater control over their hardware and operating environment.
The infrastructure challenge: GPU hosting is not ordinary rack colocation
An eight-GPU AI server introduces substantial power and thermal demands. Before ordering hardware, enterprise buyers should confirm the precise server power envelope, rack-level power allocation, power-feed design, cooling method, physical footprint, networking and maintenance access. Cooling requirements differ by server configuration; liquid-cooling compatibility must be verified against the selected chassis and facility design.
A complete AI colocation assessment should include:
- Power: Committed kW per rack, A/B feeds where required, distribution and headroom.
- Cooling: Air or liquid-cooling design, thermal rejection capacity and operational redundancy.
- Connectivity: High-speed Ethernet or InfiniBand fabrics, internet transit and cross-connects.
- Storage: NVMe and networked storage throughput aligned with model training and checkpointing.
- Operations: Remote hands, hardware access, monitoring, spares and incident response.
- Commercial terms: Rack commitments, metered versus committed power, expansion rights and SLAs.
Why deploy NVIDIA B300 infrastructure in the UAE?
For enterprises operating across the Middle East, a UAE deployment can support regional infrastructure strategies, local operational coordination and access to regional connectivity ecosystems. Actual data residency, latency, regulatory and compliance requirements must be assessed for each workload and facility. The best location is one that meets the application’s technical, commercial and governance needs.
BitHash: NVIDIA B300 procurement and AI colocation planning
BitHash supports discussions around NVIDIA B300 GPU solutions and tailored enterprise colocation services. Our engagement starts with the customer’s intended workload, server configuration, rack count, power density, cooling needs, networking and growth roadmap. We then develop a project-specific commercial and technical proposal, subject to confirmed hardware availability, facility capability and agreed terms.
Planning a one-rack proof of concept or a multi-rack AI cluster? Contact BitHash to discuss NVIDIA B300 solutions, dedicated rack capacity and enterprise colocation options in the UAE. Explore BitHash Enterprise Colocation
Contact: +971 58 572 2898 | info@bithash.ae | www.bithash.ae
Frequently asked questions
How many GPUs are in an NVIDIA HGX B300 server?
The HGX B300 platform integrates eight Blackwell Ultra GPUs in its reference server architecture.
Does every NVIDIA B300 server require liquid cooling?
Cooling depends on the validated server and rack design. Confirm thermal and facility requirements with the system supplier before procurement.
Is B300 suitable for inference as well as training?
Yes. The architecture targets demanding training and inference workloads, although smaller workloads may be more cost-effective on other GPU platforms.
Can BitHash quote for multiple AI racks?
Yes. Share your rack count, server bill of materials, committed power per rack, cooling and connectivity requirements for a tailored assessment.
BitHash
Verified AnalystBitHash Infrastructure, UAE Colocation & Mining Intelligence Team