A miner can still power on, spin its fans and appear healthy while one failed hashboard removes a third of its earning capacity. That is why hashboard repair should be treated as a priority by UAE operators: it is not simply a workshop task. It is an uptime decision. Every hour that a board runs below specification, reports intermittent faults or sits waiting for diagnosis can reduce realised hashrate and weaken the economics of the machine.
For a solo miner, a single underperforming ASIC can materially change daily returns. For an industrial fleet, small fault rates multiply quickly into lost production, higher technician workload and misleading performance reports. Professional repair restores more than a board – it gives the operator reliable data on whether the miner should return to service, remain under observation or be replaced.
Why hashboards fail in working mining fleets
A hashboard is the computing core of an ASIC miner. It contains rows of application-specific integrated circuits, along with the power delivery, clock, temperature sensing and signal paths required to produce hashrate. If even one chip, connector or control path fails, the miner may lose a board entirely, report missing chips, produce hardware errors or operate at a lower hashrate.
Heat is usually the starting point. ASICs are designed to run hard, but sustained high temperatures accelerate stress on chips, solder joints and surrounding components. Dust accumulation restricts airflow, while damaged fans or poor ducting create hot zones across the board. In high-density installations, the issue is rarely one miner in isolation. Rack layout, ambient temperature, filtration and airflow balance all influence fault rates.
Power quality matters just as much. Voltage instability, unsuitable power supplies and poorly maintained connections can damage regulators and other sensitive components. Humidity, corrosion, contamination and physical handling during transport can also cause failures that only become visible once the miner is back under full load. Firmware configuration can mimic a hardware fault too, which is why replacing a board before proper diagnosis is an expensive shortcut.
Hashboard repair in the UAE starts with diagnosis
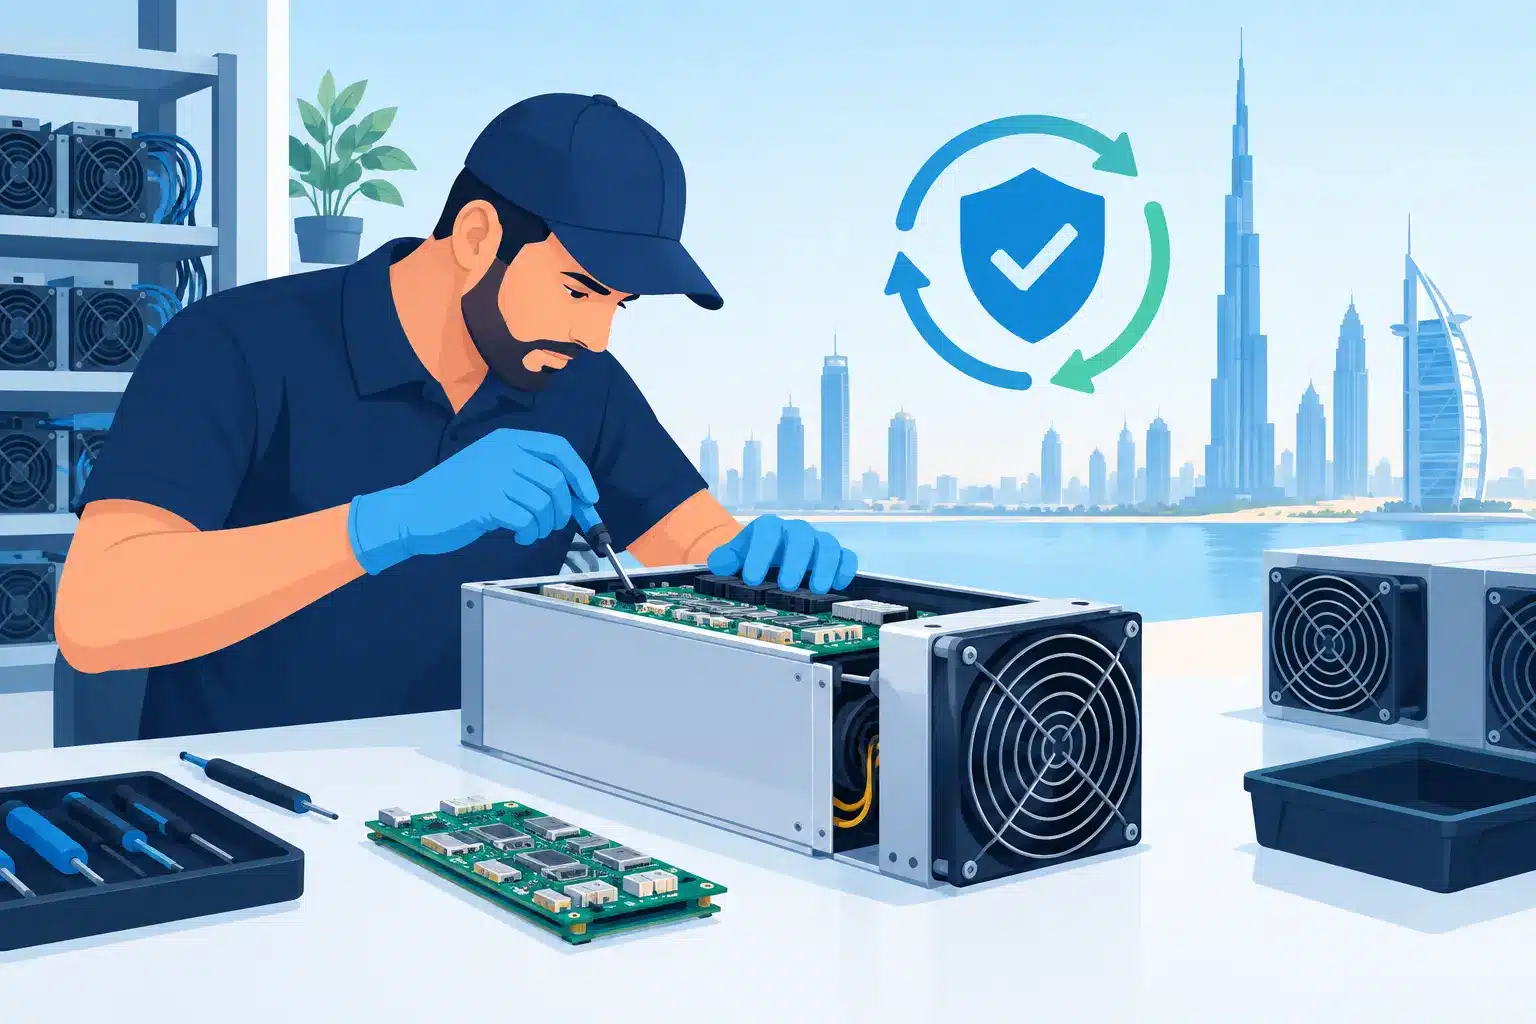
Good repair begins by identifying the actual failure, not by swapping parts until a fault message disappears. The technician should inspect the board, review kernel logs, test communication between chips, verify voltage rails and compare performance against the miner model’s expected operating range. This separates a failed hash chip from a power-delivery issue, a temperature-sensor error or a problem originating in the control board or PSU.
This process is especially valuable for miners that show intermittent behaviour. A unit might run normally after a cold start, then lose a board once it reaches operating temperature. Another may report full chip count but generate excessive hardware errors, limiting effective hashrate. These are not faults to ignore simply because the dashboard remains green.
A capable repair facility uses dedicated test fixtures and controlled burn-in rather than relying only on a brief bench test. The board needs to prove stable communication, thermal performance and expected output before it returns to a live fleet. For an operator, the meaningful outcome is not that the board has been repaired. It is that it can maintain its assigned hashrate under realistic conditions.
What a professional repair process should include
The right scope depends on the model, age and fault condition, but a disciplined workflow normally follows four connected stages:
- Intake inspection and fault logging, including serial-number tracking and a review of error codes.
- Board-level diagnostics to locate failed chips, damaged components, weak solder joints, signal faults or power irregularities.
- Component-level repair, cleaning and replacement where commercially justified.
- Load testing and burn-in before the ASIC is reinstalled, followed by monitoring during its return to production.
The final stage is where many low-cost repairs fall short. A board that passes for ten minutes may still fail after several hours of heat cycling. Burn-in reduces the chance of sending the same problem back into the mining environment, where it creates another removal, another logistics task and more lost revenue.
Repair records also matter. Fleet managers should be able to see which miner failed, what was found, what work was completed and how it performed after testing. Over time, this information exposes patterns: a specific batch with recurring faults, a rack with cooling issues, or a model that is becoming uneconomic to maintain.
Repair, replacement or retirement: make the commercial call
Not every faulty hashboard should be repaired. The right decision comes down to repair cost, expected service life, hashrate recovery, efficiency and the machine’s current earning potential. A relatively new ASIC with a contained board-level fault is often a strong candidate for repair. Restoring one-third of a modern miner’s capacity can be far more cost-effective than replacing the full unit.
The calculation changes for older hardware. If the miner already has poor joules-per-terahash efficiency, repeated board failures and high electricity costs, further repair may protect sunk cost rather than future profitability. It may be better to use recoverable parts as spares and direct capital towards newer-generation hardware or more efficient hosting capacity.
There is also a middle ground. Some miners are suitable for secondary deployment where power is cheaper or where the operator accepts lower output while waiting for a fleet upgrade. The point is to make a measured Capex and Opex decision, not an emotional one. A transparent repair quote and post-repair test result give operators the evidence to choose well.
Preventing repeat hashboard faults
The lowest-cost repair is the one that never reaches the bench. Prevention begins with operating discipline: clean intake air, adequate clearance around miners, functioning fans, correctly rated PSUs and cables, and regular review of temperature and error data. High ambient temperatures require more than turning fan speed to maximum. Operators need to assess total airflow, recirculation and the heat load across the room.
Hydro-cooled infrastructure can provide a more controlled thermal environment for compatible miners, particularly at scale. It is not automatically the best answer for every portfolio. The infrastructure investment, water-loop design and maintenance requirements must make commercial sense. But for high-density fleets, consistent cooling can reduce thermal stress and support more predictable performance.
Monitoring is the other critical layer. A miner-management platform should alert operators to missing hashboards, falling hashrate, rising chip temperatures, fan anomalies and repeated restarts. Waiting for a daily revenue report is too late. Early intervention can turn a minor temperature deviation or connector issue into a quick maintenance visit rather than a board-level failure.
Choosing a hashboard repair partner
Speed matters, but a fast repair without accountable testing is false economy. Look for a provider that understands the complete mining operation: hardware sourcing, deployment, power, cooling, monitoring and maintenance. That broader view helps technicians trace the root cause instead of treating every fault as an isolated board problem.
For UAE-based miners, local technical support can reduce downtime associated with shipping and customs while giving operators a direct route to inspection and after-sales assistance. BitHash supports ASIC owners with repair and maintenance alongside hosting and monitored infrastructure, so repair decisions can be evaluated against live fleet performance and operating economics.
Ask practical questions before handing over equipment. How are units tracked? What diagnostics are included? Is burn-in performed? Are repair recommendations clearly separated from replacement recommendations? What happens if a board fails again shortly after service? Clear answers are a sign that the provider is managing uptime, not merely processing repairs.
A hashboard failure does not have to become a prolonged loss event. With prompt diagnosis, validated repair and better operating controls, an ASIC can return to productive service with confidence. The most valuable next step is simple: investigate the first warning sign while the fault is still small enough to control.
BitHash Editorial
Verified AnalystBitHash Infrastructure, UAE Colocation & Mining Intelligence Team